Process more document volume
Classify and extract repeatable information from varied business documents without the same growth in manual entry.
Smart Scale builds document-processing systems that read invoices, contracts, applications, reports, forms, and technical files; extract the required information; validate it; send exceptions for review; and update downstream systems.
See the business story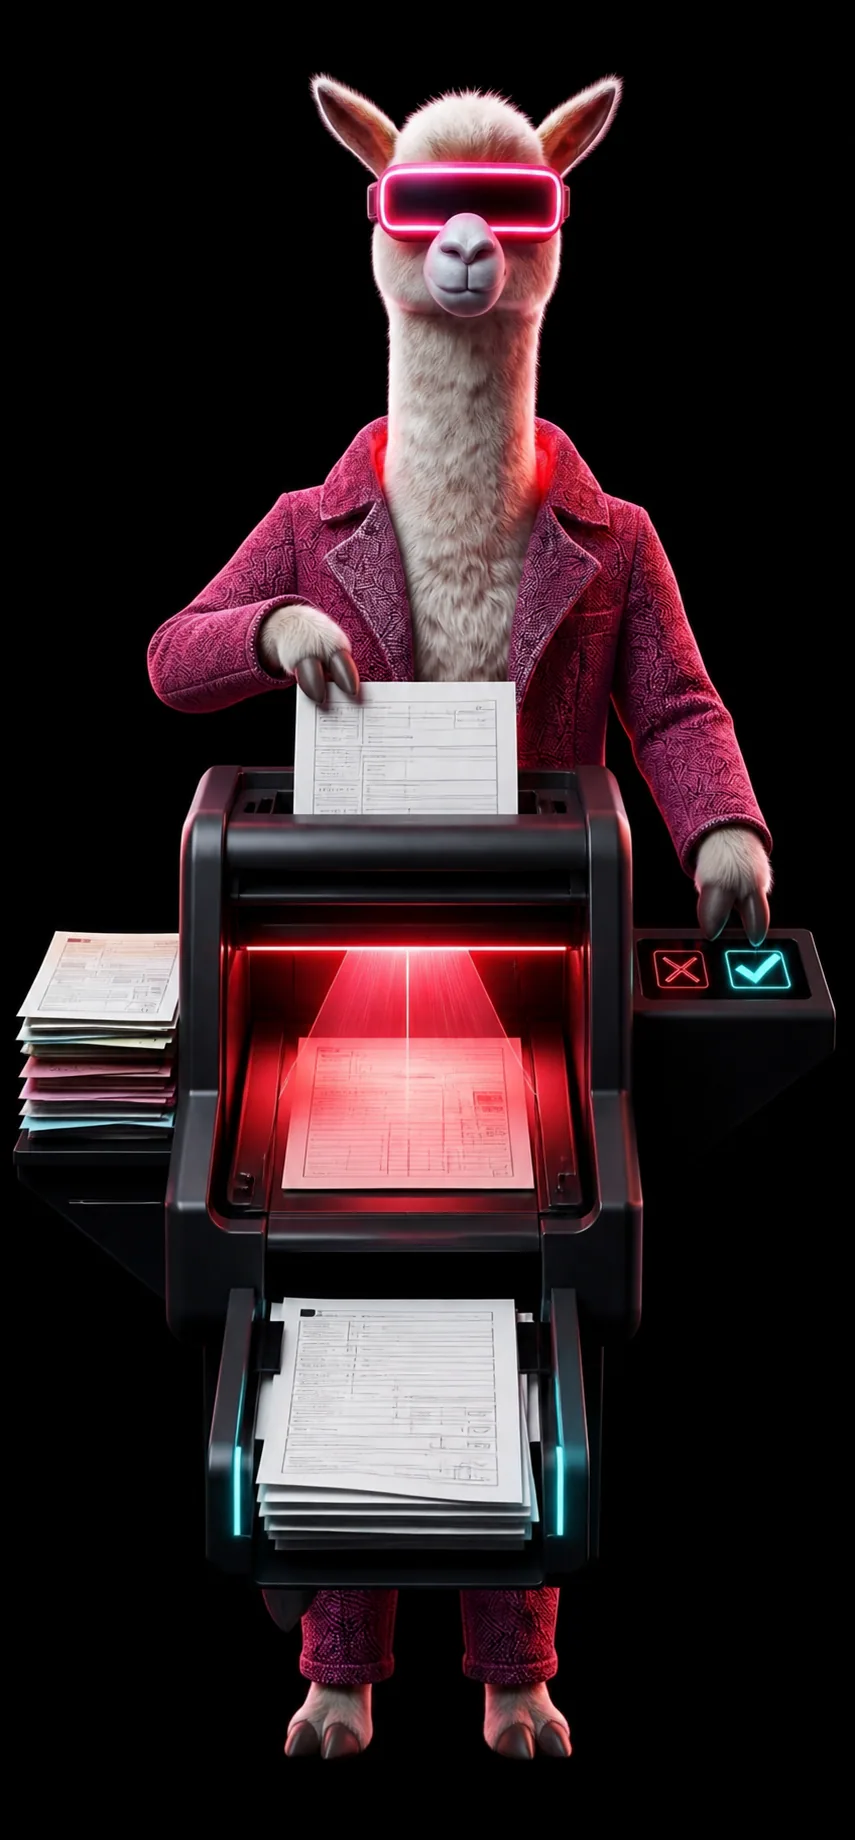 DocumentIQ
 receives files from email, portals, scanners, repositories, or upstream systems. It identifies the document, extracts fields and tables, checks the information against rules and other records, presents uncertain items to a reviewer, and posts approved data into the next process.
Classify and extract repeatable information from varied business documents without the same growth in manual entry.
Apply completeness, format, threshold, duplicate, cross-document, and cross-system checks before a record moves forward.
Show reviewers the low-confidence field, source location, business rule, supporting evidence, and pending action together.
Invoices and purchase orders
Contracts and proposals
Applications and forms
Compliance and inspection records
Technical and engineering reports
Statements and scanned records
Resumes and candidate documents
Multi-document validation packages
Finance operations
Insurance operations
Legal operations
Supply chain
Manual data entry
Inconsistent validation
Slow exception handling
Weak audit trails
 DOCUMENTIQ · 08 PART BUSINESS STORY
Teams open files, re-key information, compare fields, chase missing evidence, and decide where each case goes next.
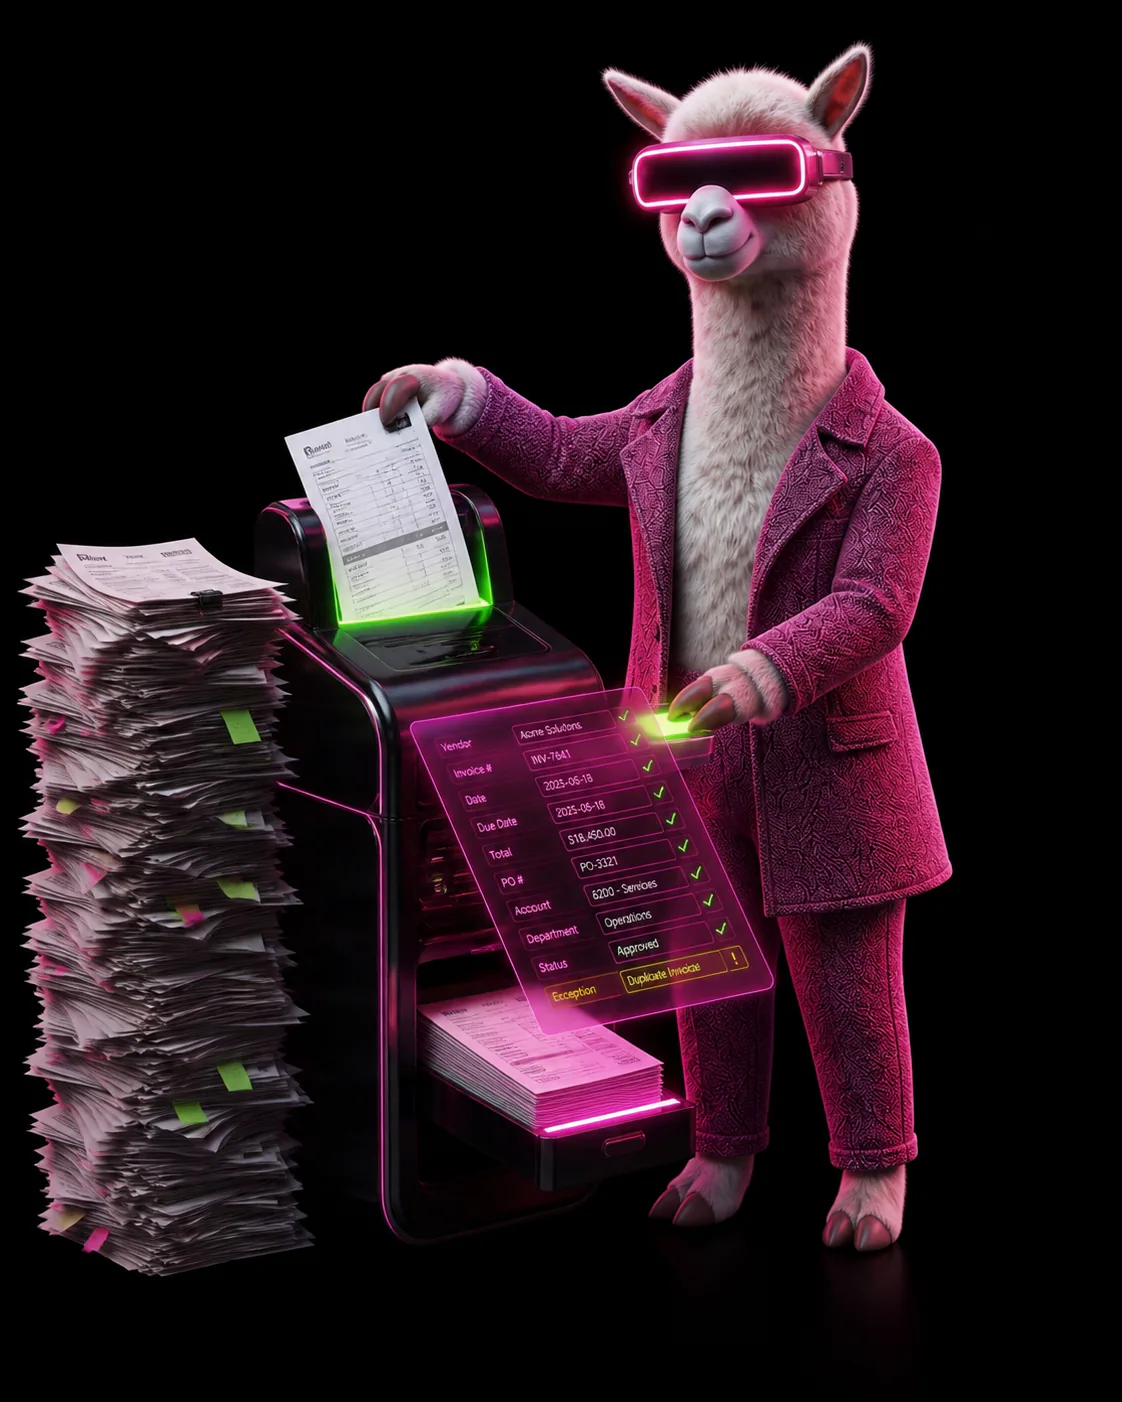
DocumentIQ receives files from email, portals, scanners, repositories, or upstream systems. It identifies the document, extracts fields and tables, checks the information against rules and other records, presents uncertain items to a reviewer, and posts approved data into the next process.
DocumentIQ accepts approved files from email, portals, repositories, scanners, or upstream systems.
The system identifies document type, retrieves required fields, checks supporting evidence, and applies business validation.
Missing, ambiguous, conflicting, or high-risk fields enter a focused review experience with the source visible.
Approved results update records, trigger workflows, create tasks, and retain the original document and decision history.
The system reduces repetitive document work while preserving the original source, every extracted value, reviewer correction, validation decision, and final system action.
Deployment begins with a defined document family, validation policy, and downstream action. Performance is evaluated at field and case level before scope expands.
The tools and connections change for every client. The simple idea stays the same: understand the need, complete what is allowed, involve a person when needed, and keep a useful record.
Receive files with source, identity, and case context.
Identify document and package type before processing.
Retrieve required fields, tables, clauses, and supporting evidence.
Apply formats, tolerances, cross-document checks, and business rules.
Present low-confidence and policy-sensitive items to a person.
Write approved results to downstream records and workflows.
Retain source, extraction, changes, approver, and final status.
This example shows the pattern. The final conversation, workflow, permissions, and actions are designed around your business.
The system identifies the package, extracts required fields, compares purchase and receipt evidence, and prepares a validated transaction.
Classify attachments
Extract invoice data
Run cross-document checks
Create the payable record
Original files
Extracted values and confidence
Validation results
Reviewer corrections
Mismatched totals, missing evidence, unusual payment details, or low-confidence fields enter a reviewer queue before any posting action.
Document and package classification
Field and table extraction
Clause and evidence detection
Multi-document comparison
Format and completeness checks
Cross-system verification
Policy and threshold rules
Duplicate and anomaly signals
Human review workbench
Reviewer correction capture
Downstream posting
Case and audit history
People remain responsible where the consequence is high. Sensitive, uncertain, unusual, or customer-requested cases move to an accountable person with the context needed to act.
Document-type-specific rules
Confidence thresholds by field
Mandatory review for consequential cases
Original-document traceability
Restricted posting credentials
Every extracted value can retain a reference to the source page or region used for review.
Access, retention, redaction, and processing location are configured around document and jurisdiction requirements.
Reviewer changes are recorded and analysed without automatically changing production behaviour.
Accuracy, confidence, review rate, failure reasons, and downstream rejection are measured by document and field type.
We agree targets from your real starting point. Results are reported from the operation; we do not invent savings or performance claims in advance.
Less routine document handling
Faster movement from intake to validated record
More focused human review
Stronger traceability from source to action
Agree what should improve, who it affects, and how the work happens today.
Choose a first scope that is small enough to control and valuable enough to matter.
Shape the customer or employee experience, workflow, integrations, and human decisions.
Configure the system with real rules, representative information, and working business connections.
Run normal, difficult, uncertain, and failed scenarios before customers or teams depend on it.
Release to a defined group with clear support, monitoring, ownership, and success measures.
Review use, quality, outcomes, handoffs, exceptions, and feedback from the real operation.
Strengthen the experience and expand only when the evidence supports the next step.